AI Programming and the Linux Workspace
Use real chat, code review and VS Code debugging for local AI assistance, then explore Linux history, kernels, distributions and simple independent terminal examples.
By the end of this lecture you should be able to
- Own the main implementation and use chat for local code assistance and debugging
- Retain candidates and run independent checks before a concrete follow-up
- Read diffs, explain the core code and disclose actual assistance
- Relate Unix, GNU and Linux and distinguish a kernel from a distribution
- Separate terminals, shells and Python and use simple file and terminal commands
- Operate the VS Code debugger and check advice against variables, call frames and execution
Contents
This lecture has two parts: AI-assisted programming and debugging, followed by Linux. A file-type counter is the example for the first part. Linux begins with the film and continues with independent hello.py and terminal examples.
The taught sequence comes first. Complete reference implementations, the directory adapter and the existing detailed material follow as optional reading.
Part 1: AI-assisted programming and debugging
Understand the LLM before asking it for help
A large language model (LLM) is a neural network with many learned numerical parameters. For the generative models discussed here, developers do not write a separate answer rule for every question. Training adjusts the parameters using many examples, allowing the model to learn relationships in language, code and context.
Training and use are different processes
- Pretraining uses text, code, documentation and other material for prediction practice. The model predicts continuations from context; training compares those predictions with the data and adjusts parameters. Solving many such tasks can develop useful representations of syntax, knowledge associations, APIs and program structure. This does not guarantee a correct answer to every question.
- Instruction and feedback training uses request/response examples and feedback to improve how a model follows requests, explains and answers. Recipes differ across models; this is a simplified common picture.
- At use time, your question, relevant code, errors and conversation context are supplied to the trained model, which generates a response. Adding code to an ordinary chat usually changes the current input, not the model parameters through immediate retraining.
Stanford CS146S’s introductory slides separate generation, training and practical capability. This lecture follows that distinction without requiring layer counts, vector dimensions or historical parameter estimates.
How a response is generated
A token is a text unit used by a model. It may be a word, part of a word, punctuation or another fragment; the tokenizer determines the boundaries. It is not necessarily one character or one whole word. Given the available context, the model predicts a probability distribution over the next token, selects a continuation, appends it, and repeats until stopping. Selection may be stochastic rather than always choosing the highest-probability token.
For example, The sky is admits several continuations. Once a new fragment is added, the updated context is used for the next prediction. This is a conceptual illustration, not a measured probability table from a model. The process does not consult only the preceding word’s frequency. 3Blue1Brown’s visual explanation illustrates the repeated generation loop.
Code is structured text too. Training involving code and documentation can connect syntax, APIs, descriptions and implementations; instruction training helps turn requests such as “explain this error” or “suggest a local change” into responses. The same model can therefore answer questions, explain code and produce fragments. Generating code or an explanation does not mean Python ran it, or that the model knows your current files, interpreter and entire contract. Execution evidence must be obtained separately.
Model, chat application and coding agent
| Layer | Role |
|---|---|
| LLM | Generates outputs from the supplied context |
| Chat application | Organizes requests and responses; users can paste code, errors and relevant material |
| Coding agent | Application software can execute model-requested file or terminal tools and return their results to the model |
A tool call is an action actually executed by software. Merely generating “I tested it” does not create a test result. Berkeley’s agent lecture distinguishes actions and observations; MIT Missing Semester places file and terminal tools in a concrete development workflow.
At Level 1, use chat for local help: explanations, debugging and limited code generation or revision. Edit, integrate, run and verify the code yourself. Do not ask for the complete assigned solution or let an agent operate on the project. Level 2 opens complete implementations and agent-driven editing, execution and fixes. A chat-like interface does not itself determine the workflow.
Four useful kinds of local request
- Understand code: ask about state changes, then trace them yourself.
- Produce a fragment: identify the location, scope and constraints of the small change.
- Diagnose an error: provide the smallest failing input, relevant code, full traceback, runtime and expected behavior; connect the cause to the evidence before patching.
- Review checks: ask about missing boundaries, while keeping expectations grounded in the contract.
These are ways of cooperating, not mandatory prompt wording. Stanford’s prompting slides compare concrete requests with different context. This lecture uses that comparison rather than a catalogue of prompting terminology.
Classroom task: review a file-type counter
Use the instructor-provided file-type counter to practice understanding code, spotting a mismatch and making a local revision. Establish the rules, inspect candidates/first.py, and keep inventory.py as the complete reference and check_inventory.py as independent checks. This is classroom reading and execution material, not an additional lab submission.
Download the classroom ZIP. It also includes factorial.py and .vscode/launch.json for the debugger demonstration.
Decide the behavior and provide relevant context
Level 1 permits local code generation or revision, explanations and debugging help; it does not permit asking AI for the complete solution to an assigned problem. Use chat to obtain suggestions or a limited fragment, then review, edit, run and verify it yourself. Calling a complete solution “one function” does not change this boundary.
Level 2 permits complete implementations and coding agents that create or edit project files and run or fix code automatically. The distinction is the actual workflow: a coding agent with a chat window is still an agent. Both levels require disclosure and verification.
The interface is count_extensions(names: list[str]) -> dict[str, int]. Each input element is a nonempty basename, not a path; the list itself may be empty. The contract is:
- Count only the final suffix, normalized to lower case.
- Put names without a dot, lone leading-dot names such as
.env, and trailing-dot names such asnotes.under"(none)". - Count
archive.tar.gzundergzand.config.jsonunderjson. This classifies names, not the actual contents of a file. - Count every occurrence, preserve the input list and return a fresh dictionary on every call.
This is an instructor-authored example request, not a quotation from a student’s conversation:
Here is the local code I am inspecting:
ext = parts[1]
counts[ext] = counts.get(ext, 0) + 1
L01.PDF and L02.pdf should share the pdf key, but currently use two keys.
Explain why and suggest only a change to ext.
Preserve the input and loop. Do not supply the complete function.
I will integrate, run and check the change myself.
Paste the relevant snippet, contract and observed result rather than your whole computer. Ask for an explanation or a familiar equivalent when unfamiliar syntax appears. Solo assignment 1 remains Level 0 and must not be handed to an AI for generation or rewriting.
Four real chat cases: context, reply and your own checks
The Chinese requests and quoted replies below are from the actual classroom DeepSeek Chat conversations. Code and constraints are retained. A model reply and an independently executed check are different evidence. Preparing an erroneous snippet for diagnosis does not mean DeepSeek wrote that error.
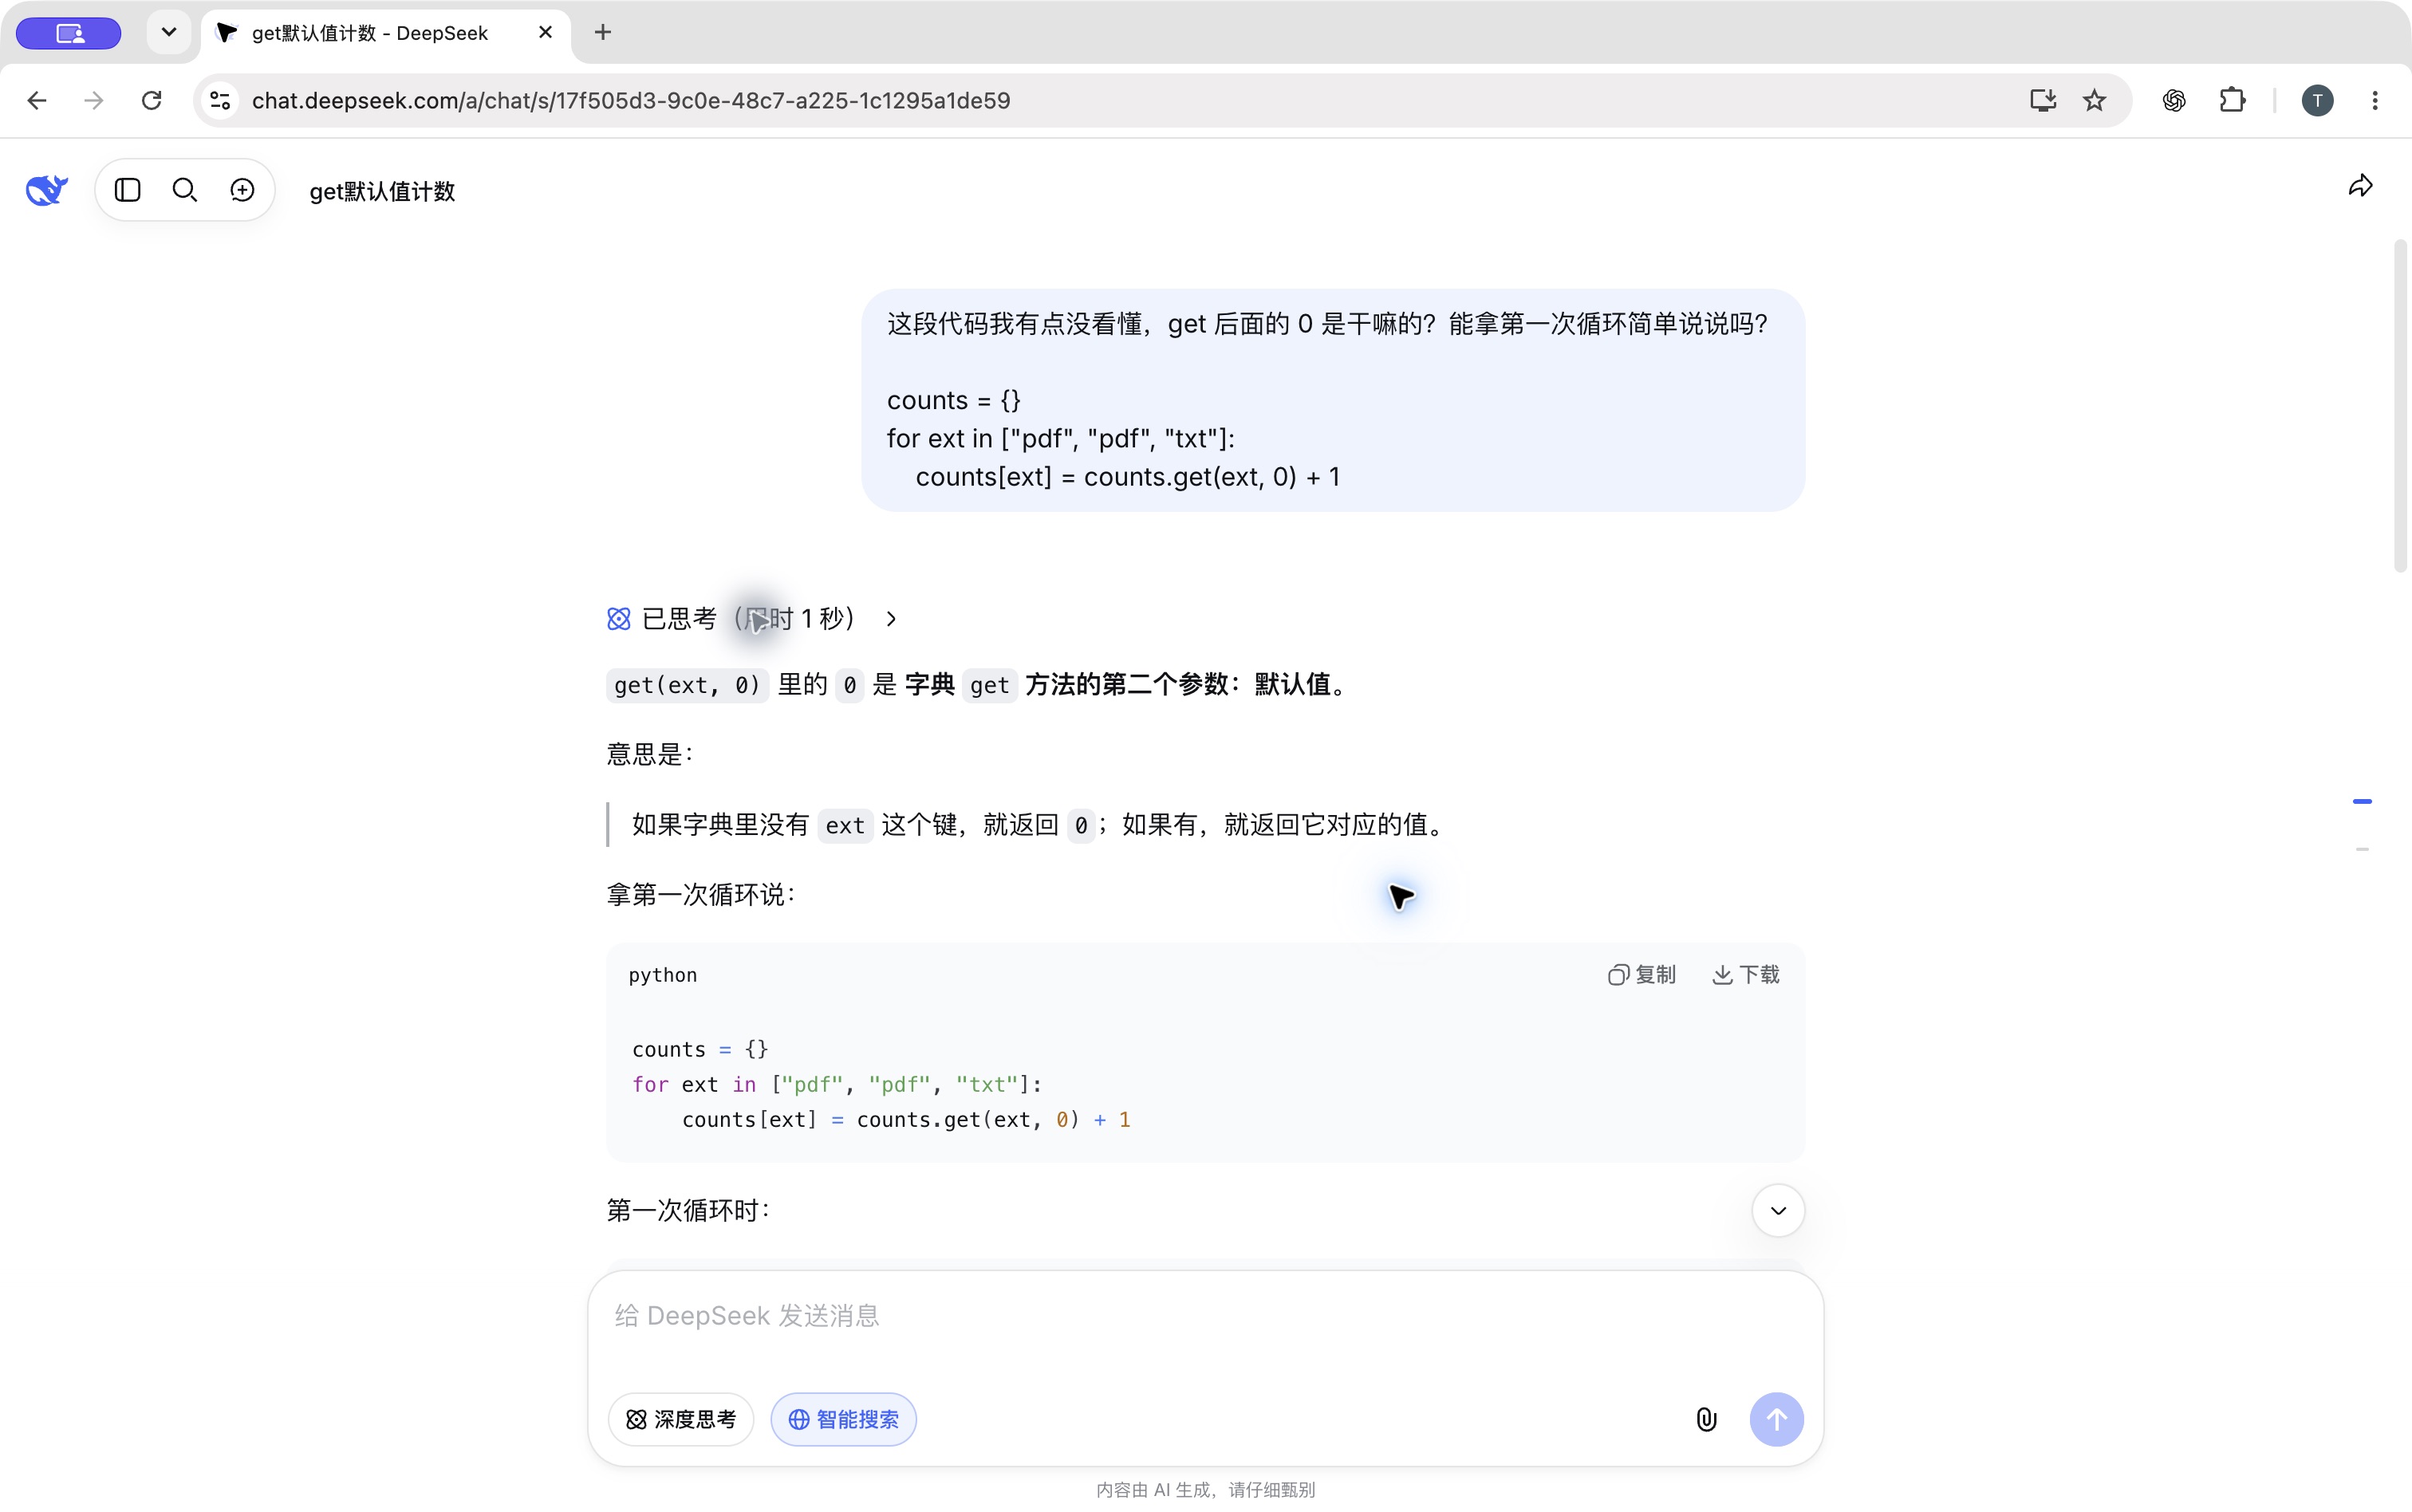
1. Understand the default argument to get
Actual request, including code:
这段代码我有点没看懂,get 后面的 0 是干嘛的?能拿第一次循环简单说说吗?

counts = {}
for ext in ["pdf", "pdf", "txt"]:
    counts[ext] = counts.get(ext, 0) + 1
Reply excerpt:
如果字典里没有 ext 这个键,就返回 0;如果有,就返回它对应的值。
In the first iteration, get returns 0 for the absent key pdf. After adding one and assigning it, counts is {'pdf': 1}. Run the following instrumented version yourself; it does not claim the chatbot ran it:
counts = {}
for ext in ["pdf", "pdf", "txt"]:
    counts[ext] = counts.get(ext, 0) + 1
    print(ext, counts)
Actual conversation screenshot.
2. Supply adjacent code before accepting a local change
The initial request described the grouping issue:
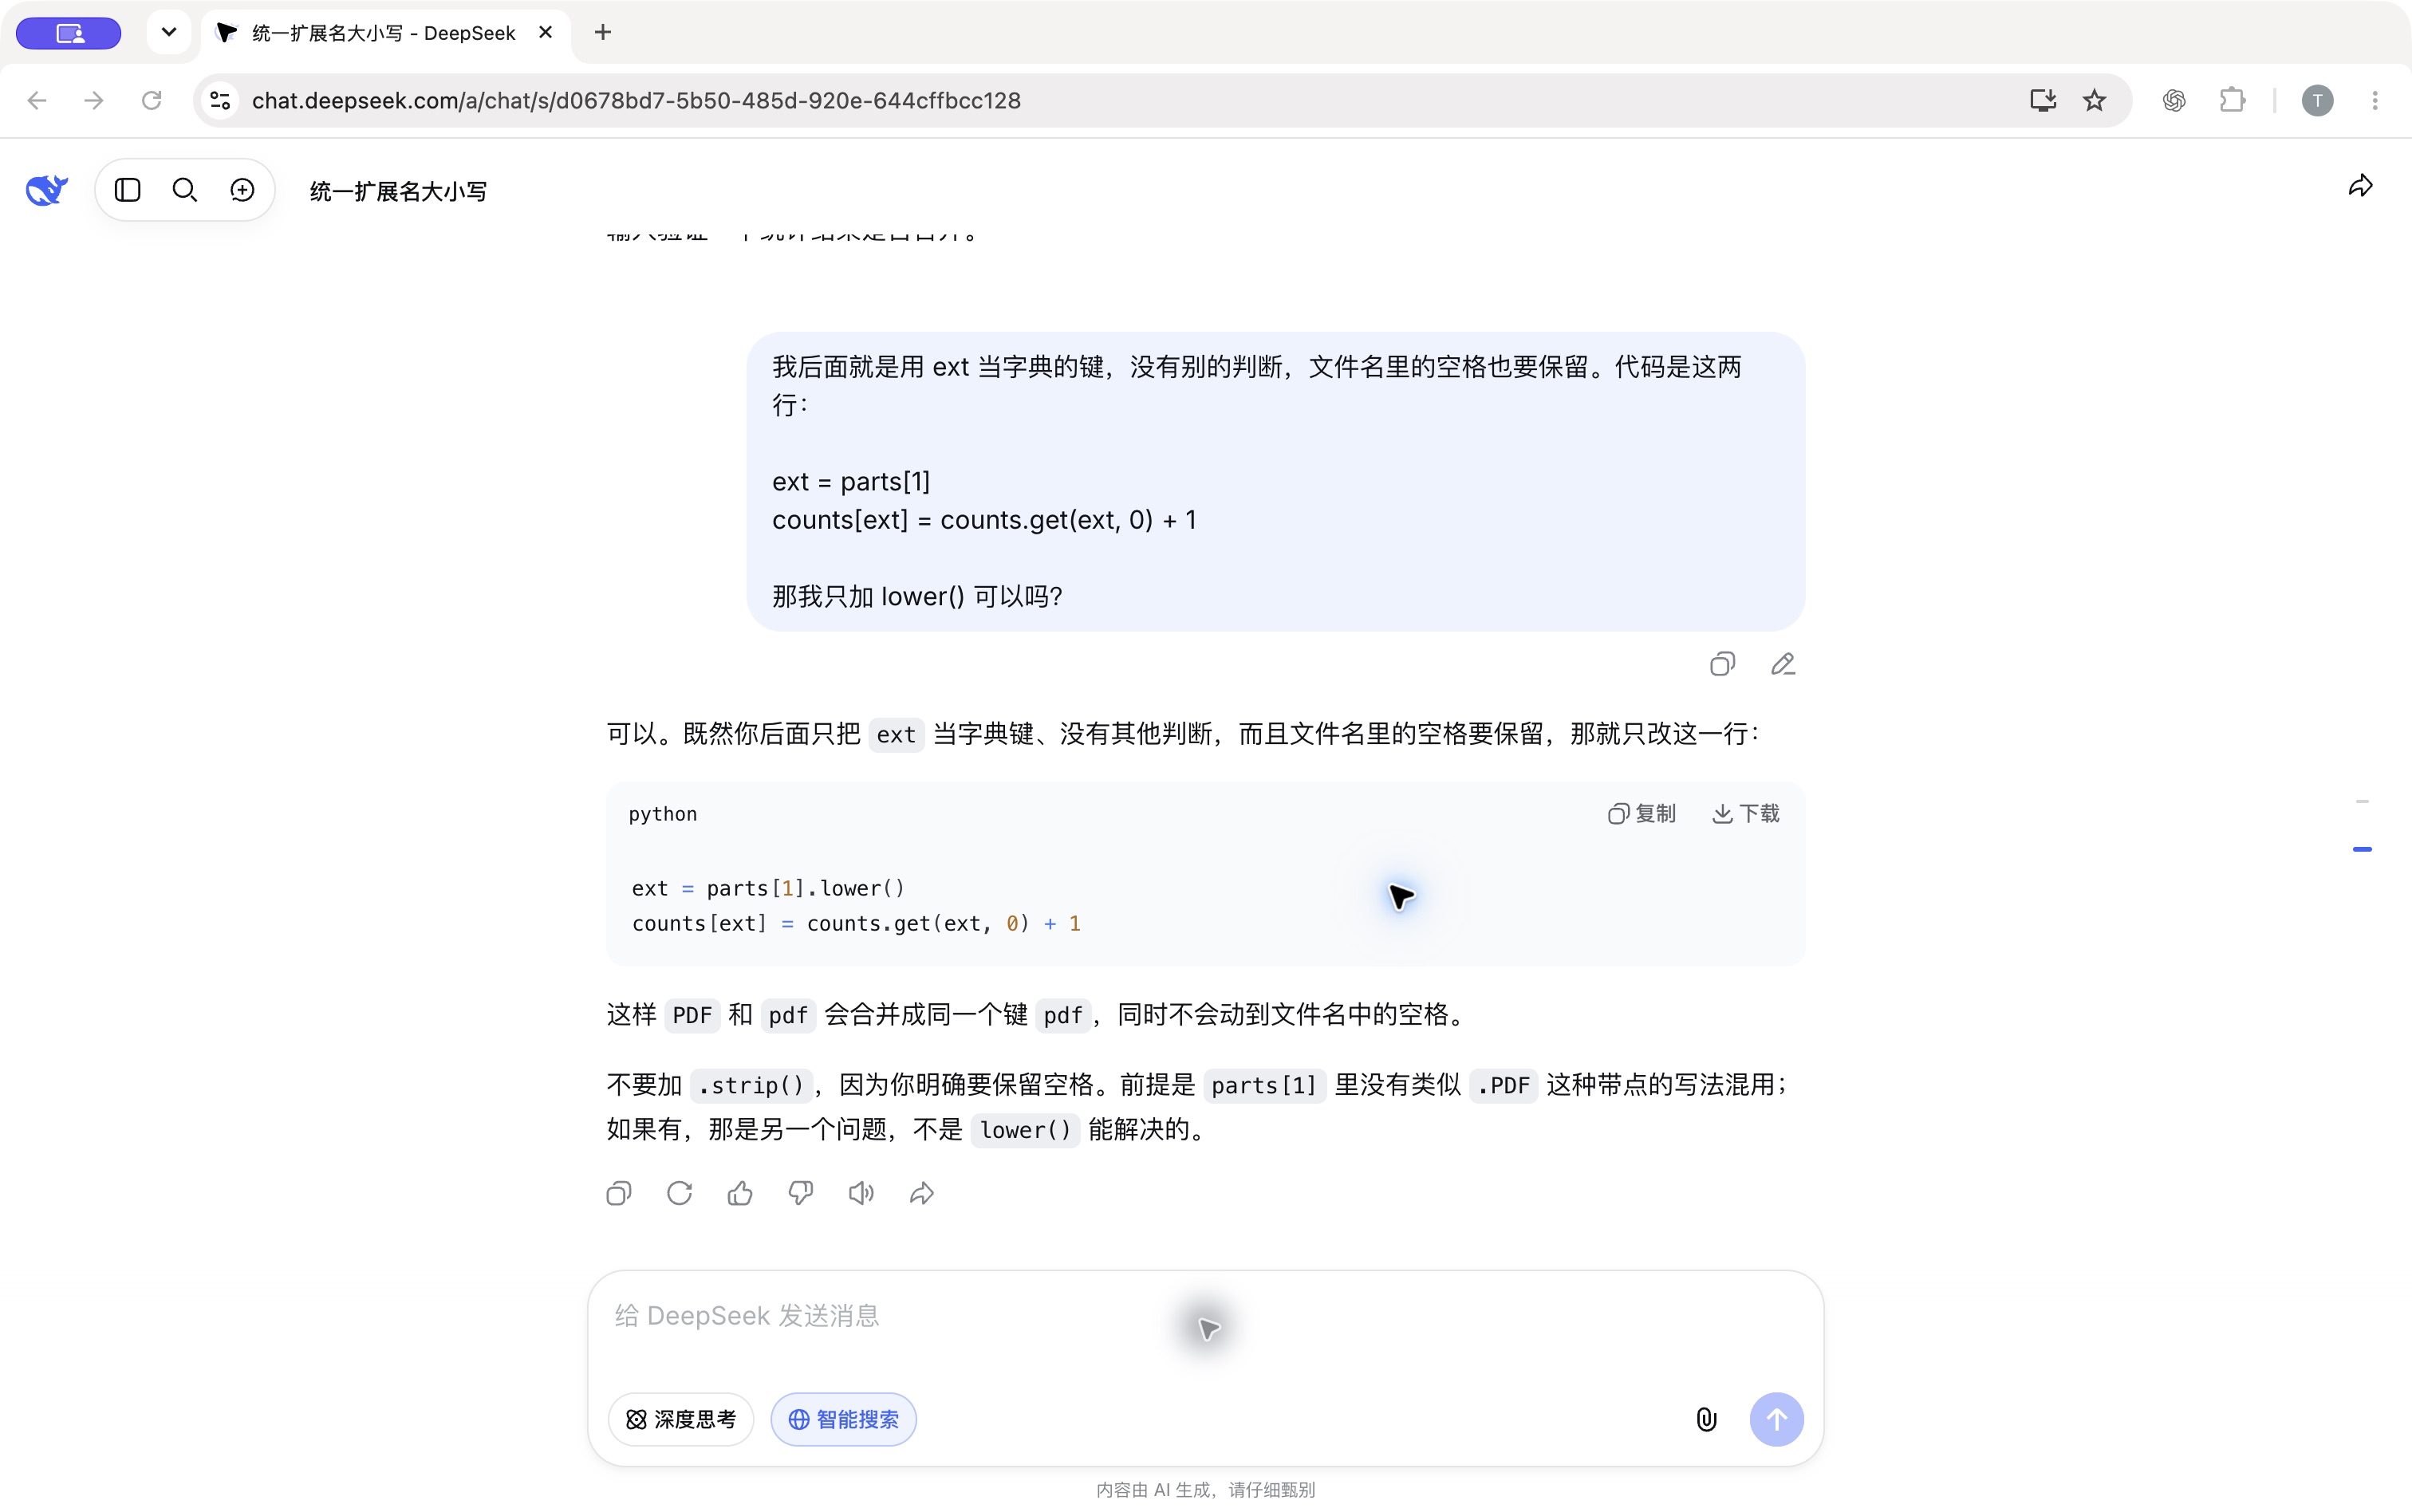
我发现 PDF 和 pdf 被分开统计了。我想把它们算在一起,是不是只要改 ext = parts[1] 这一行?其他地方先不动。It omitted adjacent code. The reply proposed lower(), and also mentioned strip(). The follow-up supplied the code, its use as a dictionary key and the whitespace constraint:
我后面就是用 ext 当字典的键,没有别的判断,文件名里的空格也要保留。代码是这两行:

ext = parts[1]
counts[ext] = counts.get(ext, 0) + 1

那我只加 lower() 可以吗?
Reply excerpts:
这样 PDF 和 pdf 会合并成同一个键 pdf,同时不会动到文件名中的空格。 不要加 .strip(),因为你明确要保留空格。
The accepted local change is:
ext = parts[1].lower()lower() creates a new suffix string. Counting uses that local key and leaves the original filename list unchanged. Check the merged PDF/pdf result and rerun existing no-suffix cases. Whether strip() belongs here depends on the contract, not on the fact that an assistant proposed it.
Actual conversation screenshot.
Check side effects: two names, one list
This example shows why we also check whether the input was changed. Assignment does not copy the list, so both prints see the changed first filename. A local suffix normalization need not mutate that list.
def prepare(names):
    result = names
    result[0] = result[0].lower()
    return result

files = ["L01.PDF", "L02.pdf"]
print(prepare(files))
print(files)
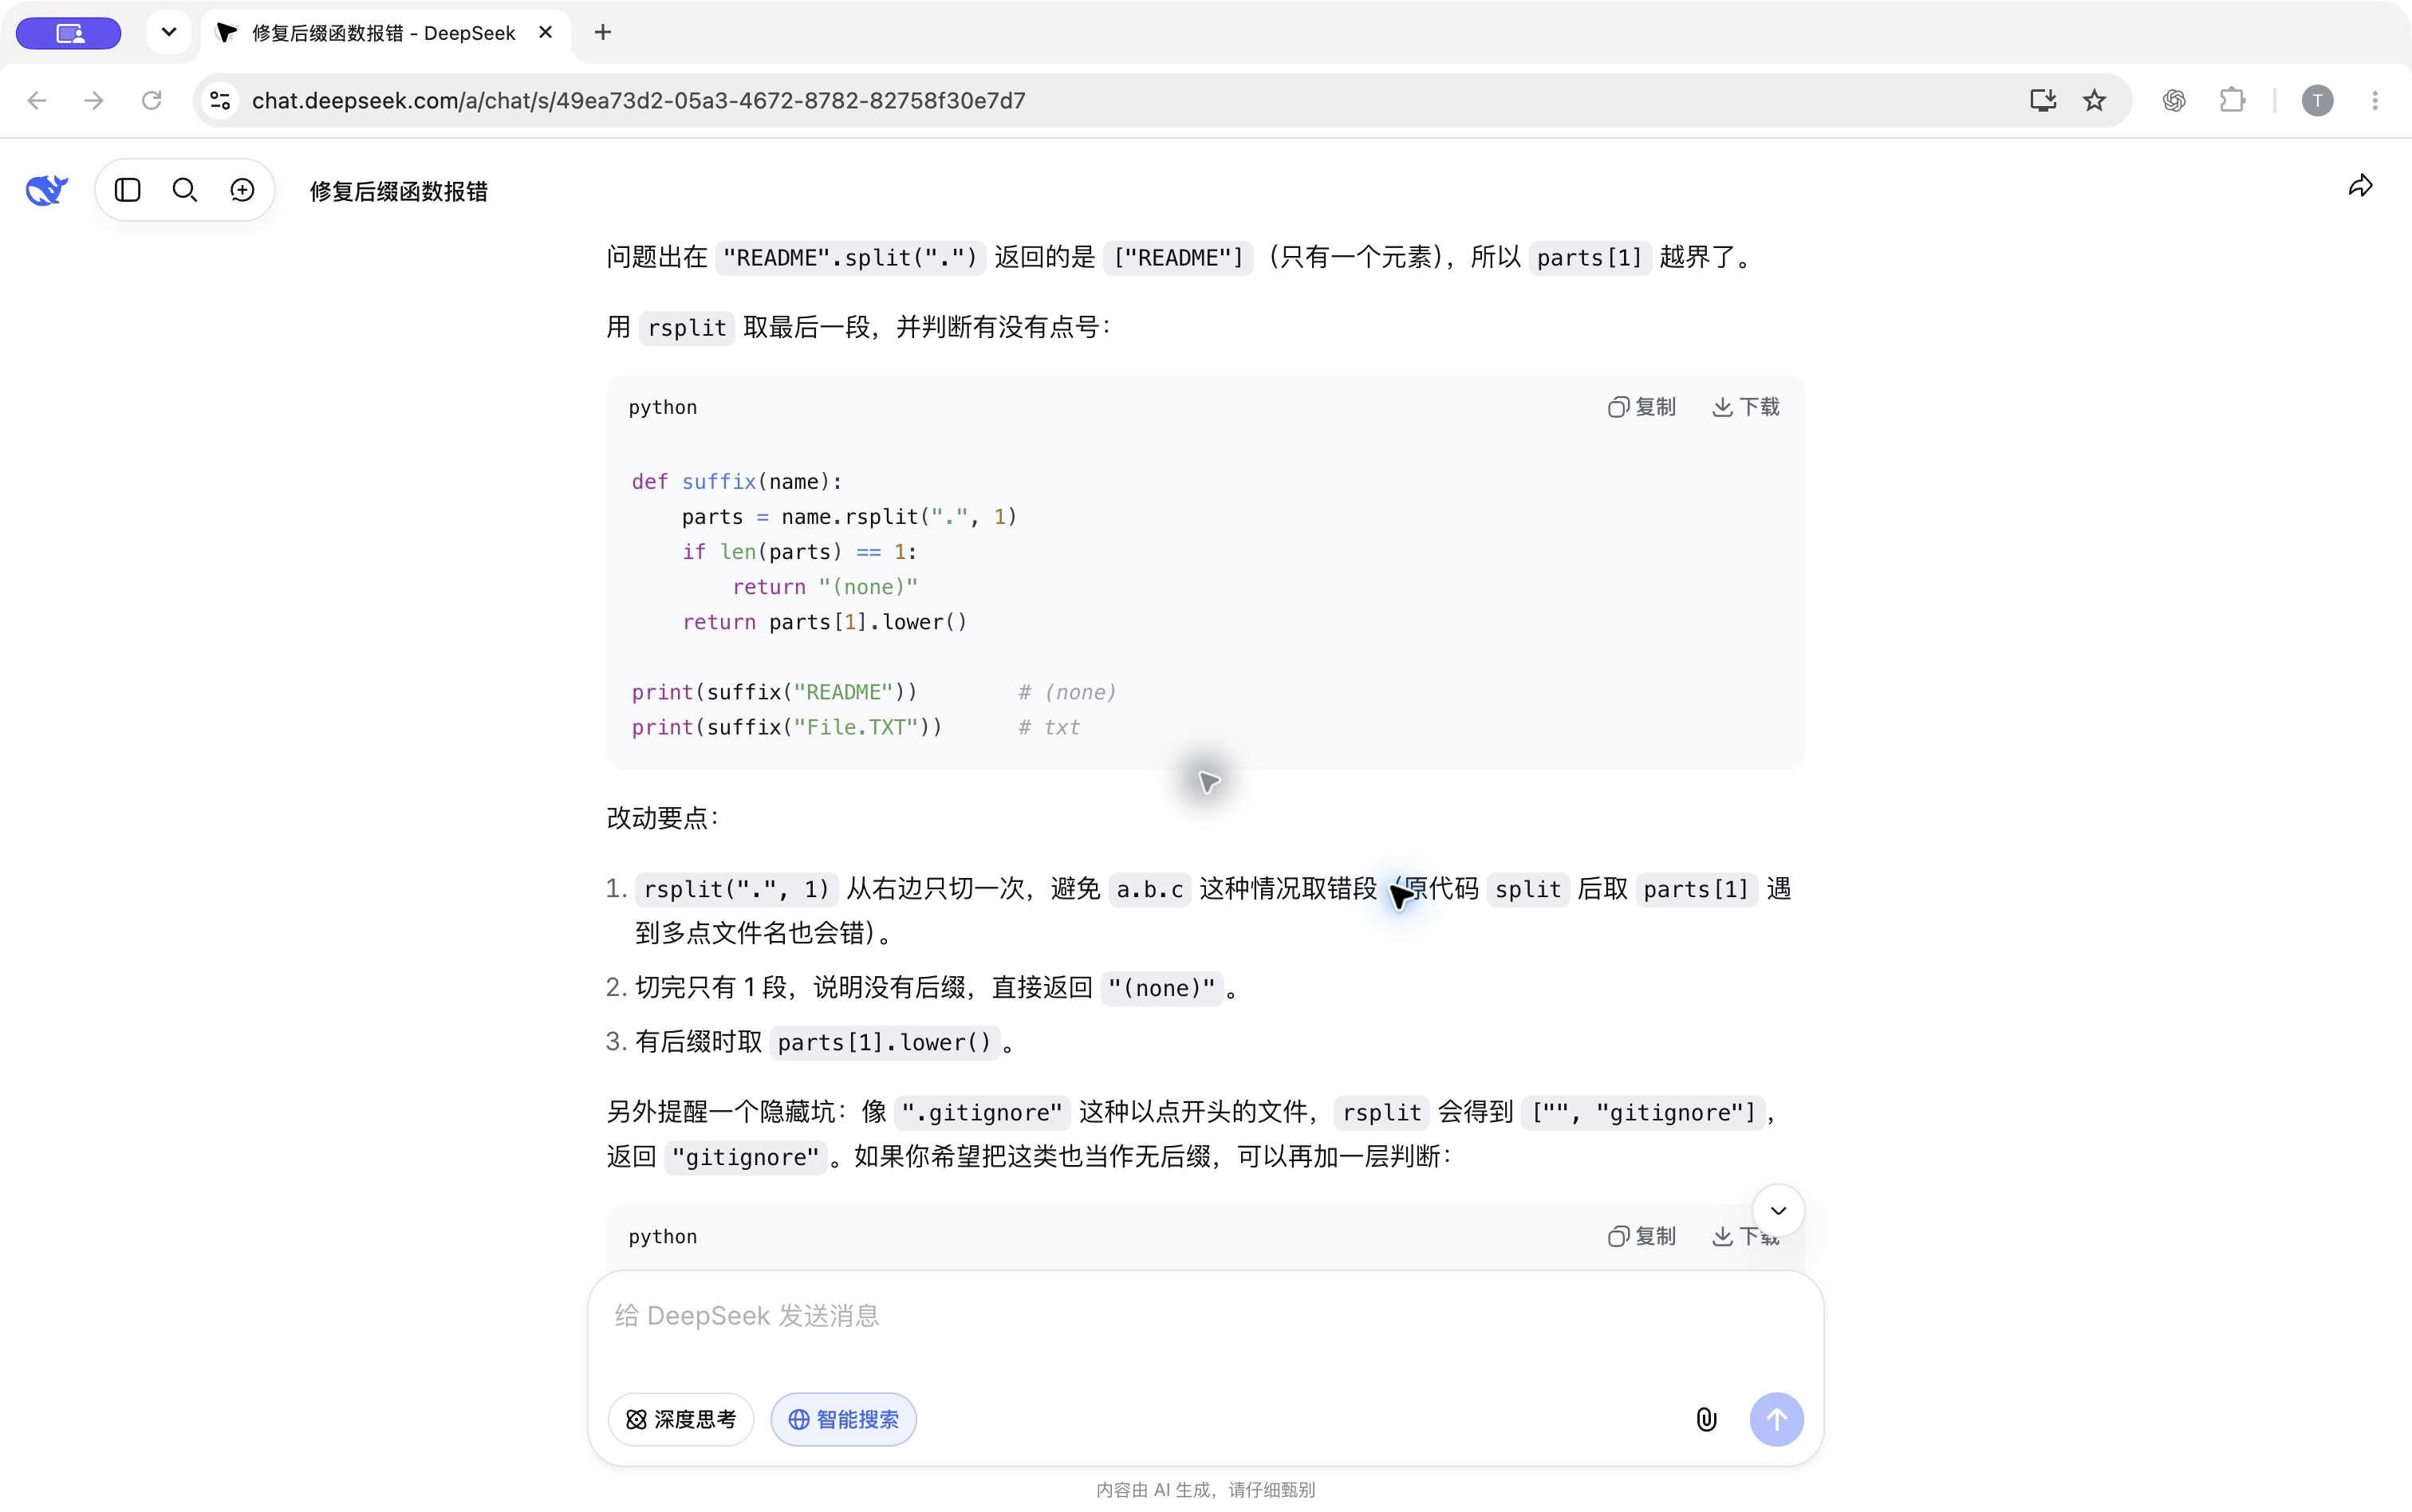
3. Send code, input, expected behavior and the complete traceback
The actual request explained that README has no suffix, should return (none), and asked for a local revision. It included this code:
def suffix(name):
    parts = name.split(".")
    return parts[1].lower()

print(suffix("README"))
The complete error sent with it:
Traceback (most recent call last):
  File "debug_suffix.py", line 5, in <module>
    print(suffix("README"))
          ~~~~~~^^^^^^^^^^
  File "debug_suffix.py", line 3, in suffix
    return parts[1].lower()
           ~~~~~^^^
IndexError: list index out of range
Reply excerpt:
问题出在
"README".split(".")返回的是["README"](只有一个元素),所以parts[1]越界了。
The next function is DeepSeek’s actual first proposal, followed by three inputs that we used to check it ourselves:
def suffix(name):
    parts = name.rsplit(".", 1)
    if len(parts) == 1:
        return "(none)"
    return parts[1].lower()

for name in ["README", "File.TXT", "notes."]:
    print(name, repr(suffix(name)))
Actual output:
README '(none)'
File.TXT 'txt'
notes. ''
README no longer raises an exception, but notes. returns an empty string. The existing contract requires (none), so the proposal is incomplete. A correct diagnosis of the exception does not establish correctness on all inputs.
Actual conversation screenshot.
4. Ask for test ideas without claiming implementation review
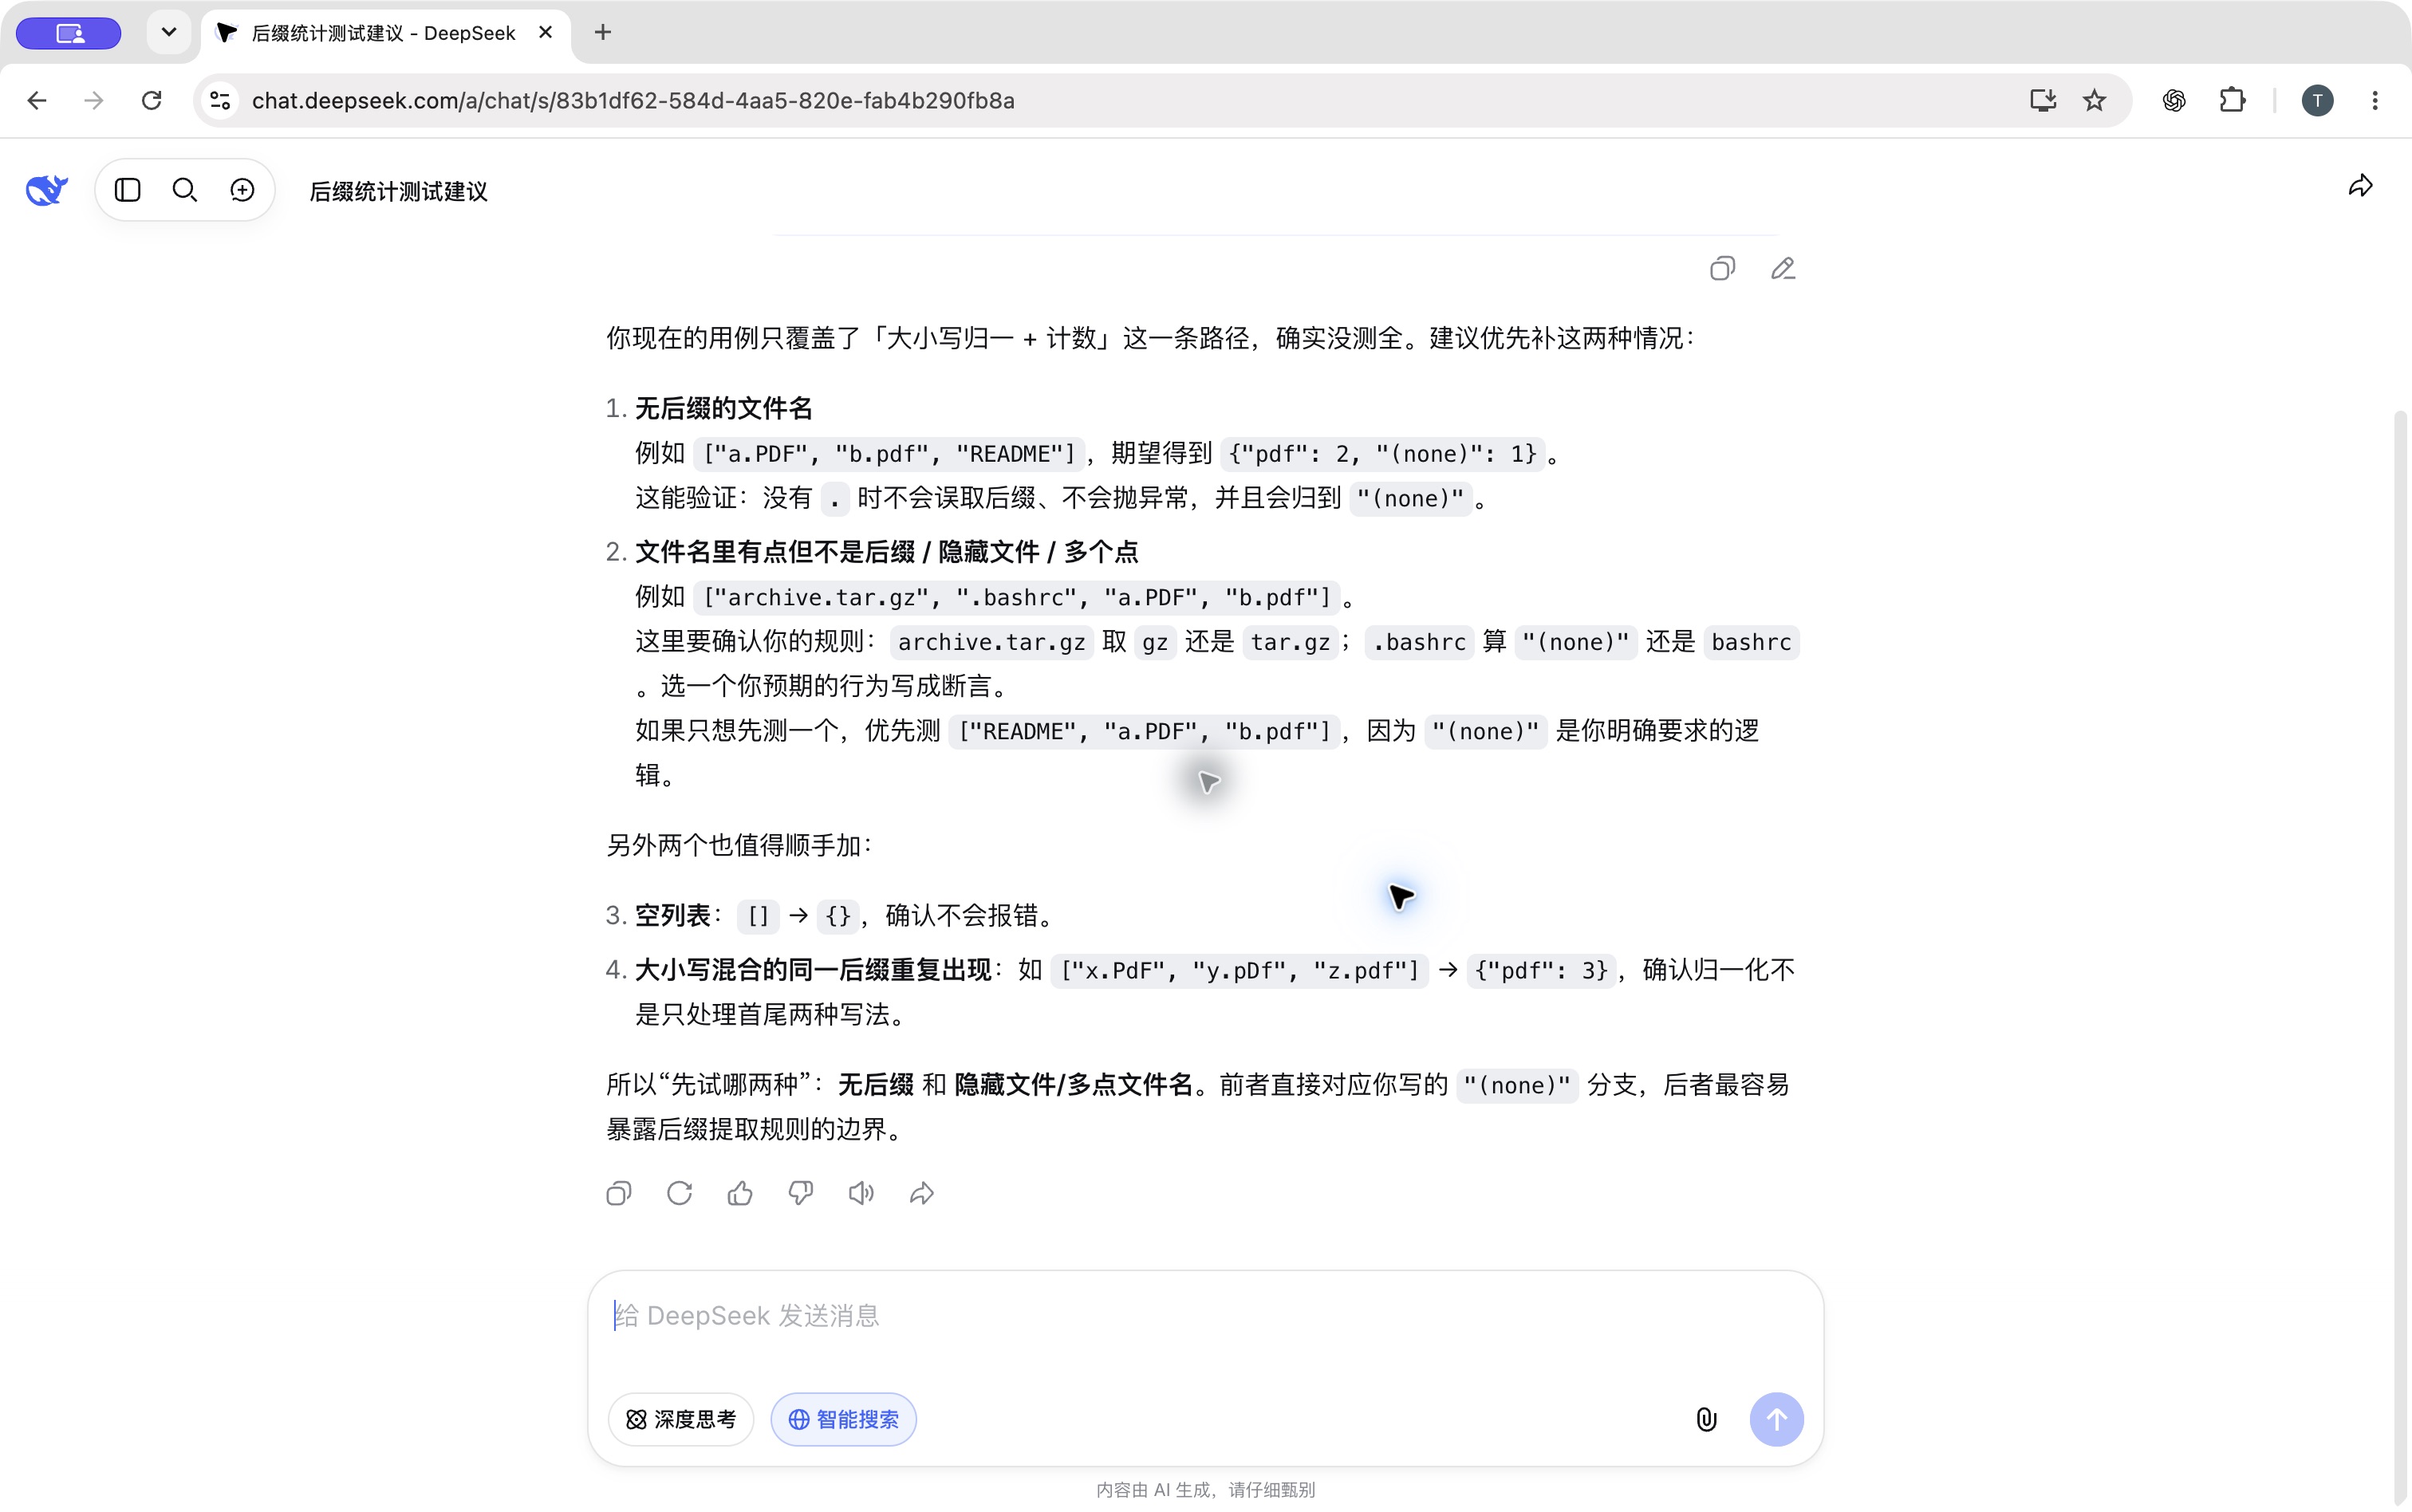
This actual request supplied requirements and the cases already tried, but no implementation:
我写了个统计文件后缀的小函数,PDF 和 pdf 要算一类,没有后缀的算 "(none)",也不能改原来的文件名。我目前只试过 ["a.PDF", "b.pdf"],结果是 {"pdf": 2}。这就算测全了吗?还应该先试哪两种情况呀?Reply excerpt:
所以“先试哪两种”:无后缀 和 隐藏文件/多点文件名。
This supplies test directions, not proof that a particular function is correct. We obtained the following results by running the complete reference ourselves. Requirements still determine the expected behavior of suffix-free, hidden and multi-dot names:
README {'(none)': 1}
archive.tar.gz {'gz': 1}
.bashrc {'(none)': 1}
Actual conversation screenshot.
Observe runtime state in VS Code, then follow up in chat
If final output is insufficient, pause the program and inspect variables and call frames. A chatbot has not observed that paused state unless you provide the code, input, paused line, selected frame and values. Reuse factorial(3) from L7 here; this is not an additional lab task.
- Install Microsoft’s Python and Python Debugger extensions. Unzip the classroom ZIP and open its complete folder through File → Open Folder.
- Open factorial.py. Use View → Command Palette → Python: Select Interpreter and select the course Python 3.13.
- Click beside line 4 to set a red breakpoint. Execution pauses before the line executes.
- In Run and Debug, select the supplied Classroom factorial(3) configuration. Use F5 / Run → Start Debugging. Ordinary Run Python File is not breakpoint debugging.
- The first stop has n=3. Continue twice to reach n=2 and n=1. Inspect Variables. Selecting the outer factorial(3) frame in Call Stack shows its own n=3, without re-executing it.
| Action | Common key | What it does |
|---|---|---|
| Step Into | F11 | Enter the call on the current line |
| Step Over | F10 | Execute the line without normally stepping through its calls |
| Step Out | Shift+F11 | Run until this call returns |
| Continue | F5 | Run to a breakpoint or completion |
An internal breakpoint can still interrupt a step. Function keys may require Fn; toolbar buttons and the Run menu are alternatives. See the official VS Code guide. The actual classroom GUI capture used local Python 3.14.7; the same paused line and n=1/2/3 frame states were independently checked with course Python 3.13.
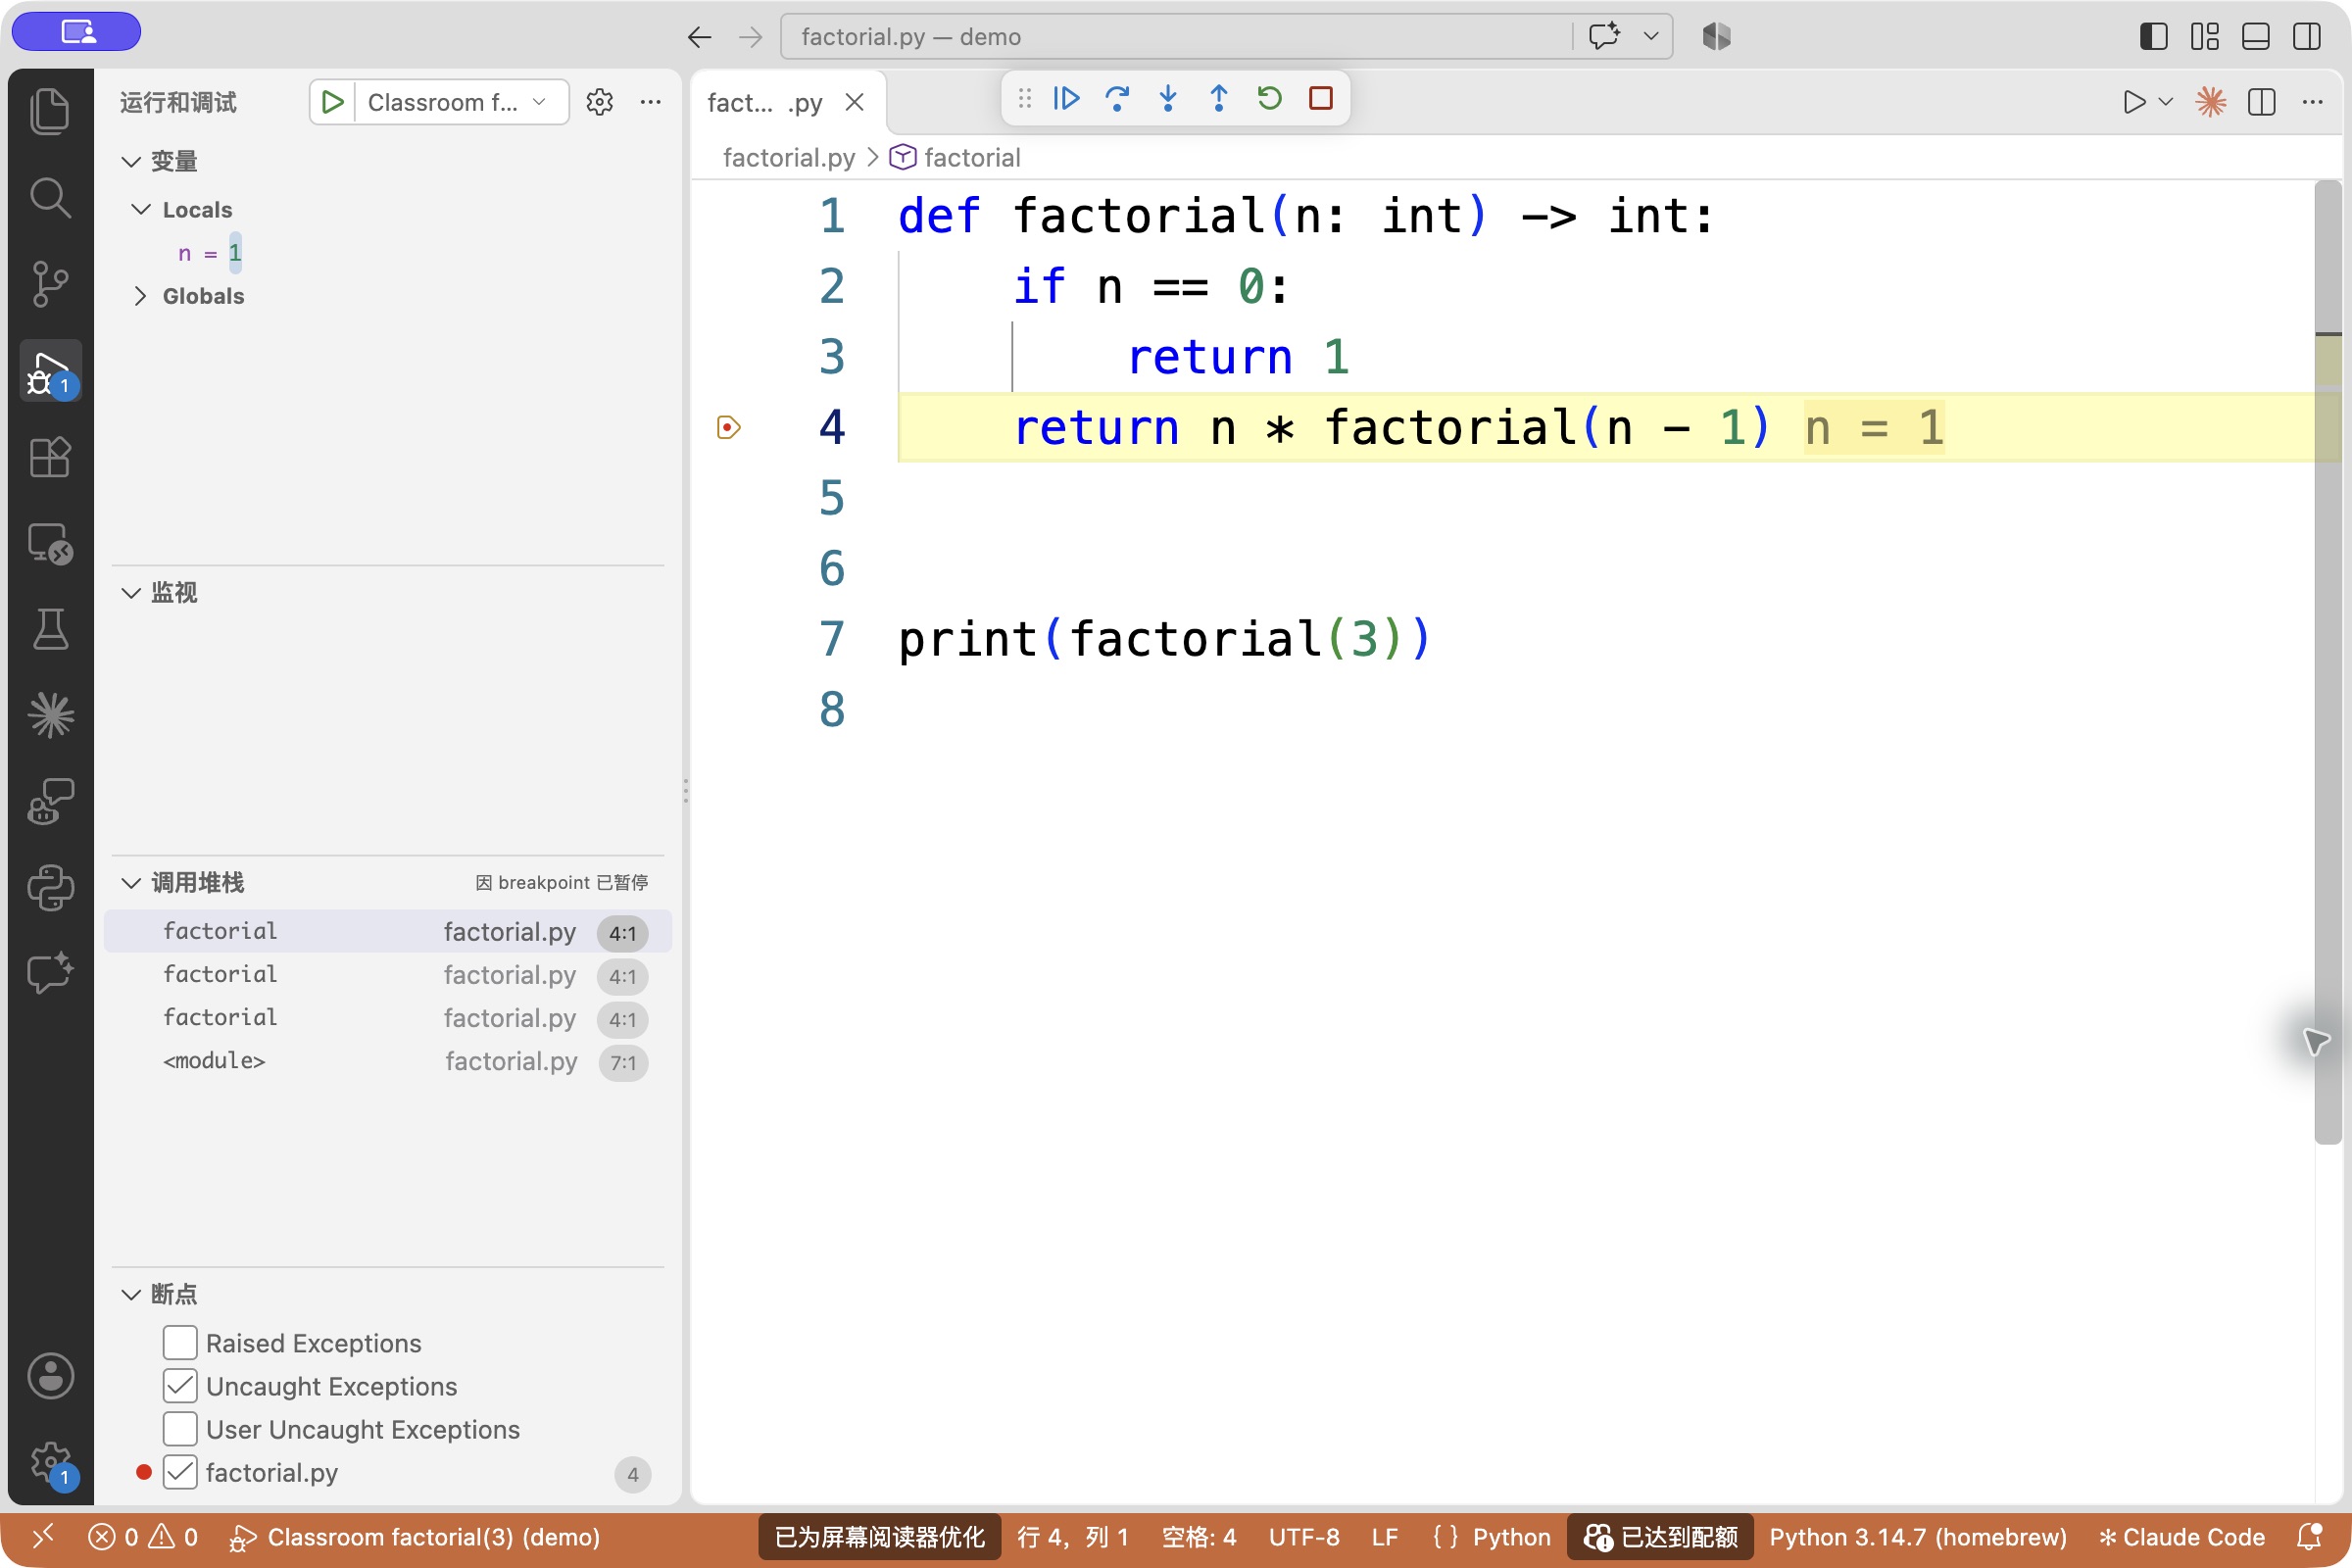
A follow-up can include the same factorial.py source, line 4, the current factorial(1) frame’s n=1, and the selected outer factorial(3) frame’s n=3, then ask why the values differ. Supply both code and state. This is a suggested follow-up format, not another claimed real conversation.
Ruff adds static checks, a debugger reveals a particular execution, and independent tests check selected behavior. Part 1 ends with context → local assistance → your own editing/debugging → execution and checks.
Execution also requires CPU time, memory and file services. Part 2 uses the film to introduce the operating system, then practices independent terminal examples.
Part 2: understand and use Linux
From Unix and GNU to Linux
Unix began at Bell Labs in 1969. This authentic archive photograph shows Thompson and Ritchie with a PDP-11 in the early 1970s; the photograph’s date is not the date of Unix’s creation.
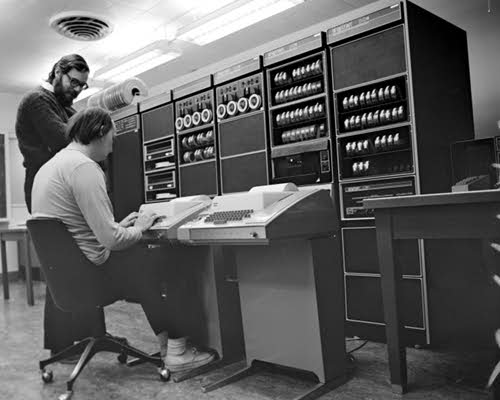
Image and historical account: Bell Labs archive. Useful tasks, including text processing, helped the system develop. Terminals connected people to a shared machine.
The GNU project was announced in 1983 with the aim of building a free software system and tools. In 1991, University of Helsinki student Linus Torvalds began the Linux kernel project and announced it publicly in August. Linux is an independently written Unix-like kernel, not renamed Unix source code. GNU history, Linux Foundation account.
Photo: kuvaaja / Linuxmag.com, 2004, original and CC BY-SA 3.0 license, uncropped. This is not a photograph of the 1991 announcement.

The original Linux 0.01 release notes, preserved by kernel.org, describe limited early hardware support and the need for a shell, compiler, libraries and other software. A kernel and a complete usable system have different scopes. Open source permits reading, modification and collaboration under licenses; it does not remove license conditions.
What does the kernel manage?
A browser, music player and Python program can run together. The kernel schedules processes, manages memory and address spaces, and provides file, network and device access through components such as filesystems and drivers. The Python interpreter handles Python syntax and dictionary operations. File reads, process creation and terminal output require system services. Linux kernel documentation.
For this particular terminal invocation:
Terminal displays interaction
    ↓
Bash interprets a command and starts Python
    ↓
Python executes hello.py
    ↓ when file, process or output services are needed
System calls → kernel → filesystems, drivers and hardware
GUI applications may launch programs directly; a shell is not mandatory for every program. Multiple cores can run work in parallel, while one core can also schedule different tasks. An application does not permanently own one CPU core.
Kernel, distribution, desktop, terminal and shell
| Component | Responsibility in this example |
|---|---|
| Linux kernel | Process, memory, device and file services |
| A distribution such as Ubuntu | Packages the kernel with tools, libraries, package management and applications |
| Desktop environment | Graphical windows, launchers and file management |
| Terminal program | Displays text input/output and hosts terminal sessions |
| A shell such as Bash | Interprets commands, redirections and pipelines, and launches programs |
| Python interpreter | Executes Python source |
Ubuntu is a Linux distribution; the Linux kernel is one of its components. A distribution combines, configures and maintains the kernel with tools such as Bash, libraries, software management such as apt, and applications. People often use “Linux” broadly for such systems; the installed distribution might be Ubuntu, Debian GNU/Linux or Fedora Linux. Desktop and application choices depend on the distribution, edition and installation. Ubuntu project.
Linux systems can have graphical desktops; servers can omit them. Systems using the Linux kernel need not share the same GNU tools or userspace. One desktop screenshot cannot represent every Linux system.
Practical differences from Windows and macOS
| Situation | Common Windows environment | Common Linux environment |
|---|---|---|
| Paths | C:\Users\Ana\project | /home/ana/project, with filesystems mounted under a single / root |
| Filename case | Commonly insensitive by default; configurable per directory | Common home filesystems are sensitive; mounted filesystems may differ |
| Shell | PowerShell, cmd and other choices | Bash and other choices |
| Software tools | GUI installers, stores and package managers | Distribution package managers and other installation methods |
Both systems support permissions, graphical interaction and command-line tools. Neither “Windows has no terminal” nor “Linux only has a text screen” is a useful distinction.
WSL 2 runs a real Linux kernel in a lightweight VM on Windows. A Windows C: drive is typically mounted at /mnt/c in that environment. Check the actual path, file location and interpreter. WSL architecture, filesystems and case behavior.
macOS uses the XNU kernel. Many Unix-style commands look similar, but XNU is not the Linux kernel. BSD tools on macOS and GNU tools commonly used on Linux can have different options: consult the current environment’s help. Apple XNU.
Practice with a few independent terminal examples
Create a directory in your own practice location. Use an editor to save hello.py containing print("hello"):
mkdir -p terminal-demo
cd terminal-demo
touch notes.txt
# Save hello.py in the editor before running it
python3 hello.py
The program prints hello. touch creates an empty file or updates timestamps; it does not write code or empty existing files. Use pwd to locate yourself, quote paths containing spaces, use Tab for completion and check python3 --version.
Add a small helper.py file, then find and count the two Python files:
find . -type f -name '*.py' | wc -lThis example produces 2. find selects .py regular files under the current directory. The pipe passes path text to wc -l, which counts newline characters. Filenames here contain no newline, so each path occupies one line. The presentation lines of ls -l are not an exact file count.
Save program output and find a line of source:
python3 hello.py > output.txt
cat output.txt
grep -n -F 'print(' hello.py
cat prints hello; grep prints 1:print("hello"). -n adds line numbers; -F matches literal text. > overwrites, >> appends, and a plain > does not capture stderr. See the find manual and grep manual.
Ctrl+C interrupts a foreground command. Up and Ctrl+R recall history. Consult man, --help or the shell’s help; q commonly exits a pager.
Linux recap
- The kernel manages CPU, memory and devices.
- A distribution combines the kernel, tools, libraries and applications.
- A shell interprets commands and starts programs.
The taught sequence ends here: explain the system layers, locate a directory, run Python, search files or text, save output and find help.
What follows is optional reference material beyond the taught sequence.
Optional reading: complete references and the directory adapter
The following material supports independent reading and reproduction. It is not a project-integration task for the Linux half of the lecture.
Complete reference implementation
The following is instructor-provided reading material, included in full for independent execution and explanation. Showing complete textbook code does not permit students to ask AI for a complete assigned solution at Level 1. Its actual authoring history is unchanged: this course-authoring session generated and ran the function; the earlier version used ext = parts[1] and a later clarification added .lower(). The student workflow demonstrated here asks chat only for that local change, then integrates and runs it manually.
def count_extensions(names: list[str]) -> dict[str, int]:
    counts = {}
    for name in names:
        parts = name.rsplit(".", 1)
        ext = "(none)"
        if len(parts) == 2 and parts[0] and parts[1]:
            ext = parts[1].lower()
        counts[ext] = counts.get(ext, 0) + 1
    return counts

names = ["L01.PDF", "L02.pdf", "README", ".env", "archive.tar.gz"]
before = names.copy()
print(count_extensions(names))
print(names == before)
The actual results are {'pdf': 2, '(none)': 2, 'gz': 1} and True. rsplit(".", 1) splits at most once from the right. Only a pair of nonempty parts supplies a valid suffix. lower() creates a string assigned to local ext; the original names remain unchanged.
Independent checks and a minimal change
For ['L01.PDF', 'L02.pdf'], the clarified contract requires {'pdf': 2}. A useful follow-up gives the input, expected result, actual result and supporting rule. Preserve the original candidate. If an exception occurs, retain its complete message and traceback.
Cover empty input, mixed case, dotfiles, multiple dots, repeated names, input preservation and separate result objects. This short check is independent of earlier runnable blocks:
def count_extensions(names: list[str]) -> dict[str, int]:
    counts = {}
    for name in names:
        parts = name.rsplit(".", 1)
        ext = "(none)"
        if len(parts) == 2 and parts[0] and parts[1]:
            ext = parts[1].lower()
        counts[ext] = counts.get(ext, 0) + 1
    return counts

cases = [
    ([], {}),
    (["L01.PDF", "L02.pdf"], {"pdf": 2}),
    (["README", ".env", "notes."], {"(none)": 3}),
    (["archive.tar.gz", ".config.json"], {"gz": 1, "json": 1}),
]
for names, expected in cases:
    before = names.copy()
    assert count_extensions(names) == expected
    assert names == before
print("4 cases and input preservation: PASS")
After a revision, rerun the new counterexample and previous checks, then read the diff. Do not change an expectation merely to match a candidate when the contract has not changed. Tests can themselves be wrong; resolve the disagreement from the task. Keep a working Git checkpoint and disclose actual tools, generated scope, changes and verification. A sample declaration is not evidence that you performed its steps.
Directory adapter: optional reading
This optional material is not a task for the Linux half of this lecture. The instructor supplies the filesystem and command-line adapter; Lecture 12 explains these APIs systematically. Save the core function above together with the following adapter as inventory.py for local execution. A browser runnable block is not a way to browse your personal filesystem.
from pathlib import Path
import sys

# Add count_extensions from the independently runnable example above.

def main() -> None:
    """Instructor-provided file and command-line adapter; see Lecture 12."""
    folder = Path(sys.argv[1]) if len(sys.argv) > 1 else Path("sample-files")
    names = [item.name for item in folder.rglob("*") if item.is_file()]
    counts = count_extensions(names)
    for ext in sorted(counts):
        print(f"{ext}: {counts[ext]}")


if __name__ == "__main__":
    main()
From the dedicated demonstration directory:
python3 check_inventory.py
python3 inventory.py sample-files
python3 inventory.py sample-files > report.out
cat report.out
sample-files is relative to the working directory, not automatically to the script’s location. Write the report outside the scanned folder so it does not become an input on the next run. The tool only reads demonstration files; it neither renames nor deletes them. The course source includes this separate demonstration in slides/l08/demo/.
Additional exception-free counterexample
This retained instructor-authored candidate is distinct from the actual first DeepSeek proposal above.
def suffix(name):
    return name.split(".")[-1].lower()

print(suffix("README"))
print(suffix("archive.tar.gz"))
README becomes readme rather than the required no-suffix category.
Complete suffix-handling reference
def suffix(name):
    parts = name.rsplit(".", 1)
    if len(parts) == 2 and parts[0] and parts[1]:
        return parts[1].lower()
    return "(none)"

for name in ["L01.PDF", "README", ".env", "archive.tar.gz"]:
    print(name, suffix(name))
Regression checks should also cover empty lists, repeated names, input preservation and independent result dictionaries.
Further reading 1. Evidence before acceptance
L07 asked what a recursive function promises, how its calls make progress and whether its results are correct. Those questions are just as useful when the implementation comes from a classmate, a website or an AI assistant.
Suppose the supplied code is short, readable and passes the example. What is still unknown? Perhaps it modifies an input that should remain unchanged. Perhaps the example omits an empty input. Perhaps the result is right but the amount of work is unsuitable for the actual data.
The candidates in this lecture are constructed teaching examples, not verbatim transcripts from a particular model. Their purpose is to make the review process observable.
Generated text is not an execution log
A token is a unit used to process text: it may represent a word, part of a word or punctuation, rather than exactly one character. A language model generates subsequent tokens from its context. A code block and a convincing explanation do not, by themselves, show that the code was executed.
At Level 2, a coding agent may also operate on the project, run programs and execute tests. At Level 1 you edit and run code yourself. Inspect what was actually done:
| Evidence | What it supports | What it does not establish |
|---|---|---|
| A candidate and an explanation | One proposed implementation and rationale | That it ran or meets every requirement |
| A recorded input and output | The behavior of that execution | Correctness for all inputs |
| Test cases and their results | Whether those checks passed | Complete coverage of possible defects |
Acceptance needs the requirement, the implementation and the available evidence together. The tool can contribute to the work; the person submitting the code must still understand the adopted implementation.
Three useful failure checks
Check the API. A string has no reverse() method:
s = "hello"
print(s.reverse())
The result is an AttributeError. The existence of list.reverse() does not imply a corresponding string method. Check the documented receiver type, arguments, result and side effects.
Slicing produces a reversed string without changing the original:
s = "hello"
print(s[::-1])
print(s)
Check the input contract. This implementation handles a nonempty list, but division by zero occurs on an empty one:
def average(nums: list[float]) -> float:
    return sum(nums) / len(nums)

print(average([1, 2, 3]))
print(average([]))
If the contract excludes empty lists, that input is outside its domain. If the task requires empty input to be accepted, specify the behavior before changing the function. The candidate’s current behavior is not a substitute for that decision.
Check the runtime. Syntax and library interfaces depend on versions. This is Python 2 syntax, not valid code for the course’s Python 3.13 environment:
# Python 2 syntax, not valid in the course's Python 3 environment.
print "hello"
The example illustrates a compatibility check; it is not a claim that present-day models routinely produce Python 2.
After these checks, there are still performance and readability questions. A program can return the right answer and remain expensive to run or difficult to review.
Further reading 2. Specify the function, not just its name
Interface and behavior are different
“Merge two lists, sorted” leaves several decisions open. Are the inputs already sorted? Should duplicates survive? May the function change either input?
A useful starting point is an interface plus a behavioral contract:
def merge_sorted(a: list[int], b: list[int]) -> list[int]:
    """Merge two ascending integer lists into a new ascending list.
    Keep duplicates. Do not modify either input.
    """
    ...
The annotation describes input and result types. The docstring states ordering, multiplicity and mutation requirements. This is a specification excerpt, not a completed implementation: ... does not perform the merge.
Python does not enforce type hints automatically. This call still concatenates strings:
def twice(x: int) -> int:
    return x + x

print(twice("ab"))
A type checker or an editor can use the annotation to flag a problem. The annotation alone does not reject the call or verify the result’s behavior.
Mutation is part of the contract
Predict both printed lists:
def without_two(items):
    result = items
    result.remove(2)
    return result

values = [1, 2, 3, 2]
print(without_two(values))
print(values)
Both lines print [1, 3, 2]. Assignment did not copy the list, and remove() removed only the first match.
For a different contract—remove all matches, return a new list and leave the input unchanged—a comprehension is suitable:
def remove_all(items: list[int], value: int) -> list[int]:
    return [x for x in items if x != value]

values = [1, 2, 3, 2]
print(remove_all(values, 2))
print(values)
Check both the result and the input:
def remove_all(items: list[int], value: int) -> list[int]:
    return [x for x in items if x != value]

values = [1, 2, 3, 2]
before = values.copy()
result = remove_all(values, 2)
print(result == [1, 3])
print(values == before)
Give enough information to review the answer
A checkable request normally includes:
- a task, signature and input domain;
- ordering, duplicates, result type and allowed side effects;
- the Python version, permitted libraries and known syntax;
- normal and boundary examples with expected results;
- relevant input sizes and performance requirements.
For example:
I wrote the word-counting loop. This is the current local preprocessing:
word = token.lower()
The rule says to strip only . , ! ? ; : from both ends of each word.
Why does "cat." remain a different key from "cat"?
Explain and suggest only the change to this preprocessing line.
Do not write the full count_words function; I will integrate and test it.
This is not a universal prompt template. The punctuation rule, for instance, must match the actual task. Boundary examples make requirements explicit; they do not guarantee an error-free response.
Request small, reviewable changes
Decomposition connects directly to L07. At Level 1, write the main implementation yourself and ask about a specific condition, statement or local block when needed. Delegating the entire solution through a sequence of requests still crosses the complete-code boundary.
For a failure report, record enough to reproduce it:
Function: max_gap
Input: [7]
Expected result: 0, as specified for fewer than two elements
Actual result: ValueError from max([])
Runtime: Python 3.13
Relevant code: the construction of gaps and the final max(gaps)
“Wrong, try again” discards the useful evidence. An assistant’s diagnosis also needs checking; it is not authoritative just because it sounds plausible.
Further reading 3. Readability as part of review
Recover the behavior before refactoring
This function works on the example, but its names and nesting hide its purpose:
def f(l, D):
    R = []
    for i in range(0, len(l)):
        if l[i] in D:
            if D[l[i]] > 0:
                R.append(l[i])
    return R

print(f(["a", "b", "c"], {"a": 1, "b": 0, "c": 5}))
Its task is to retain keys whose counts are positive, keeping input order and repeated keys. Naming that behavior makes review easier:
def filter_positive(
    keys: list[str], counts: dict[str, int]
) -> list[str]:
    """Keep present keys with positive counts, in input order."""
    return [k for k in keys if counts.get(k, 0) > 0]

print(filter_positive(["a", "b", "c"], {"a": 1, "b": 0, "c": 5}))
print(filter_positive(["a", "x", "a"], {"a": 2}))
The type hints and docstring clarify this interface; their absence was not automatically a PEP 8 violation. Shorter code is not enough: check that the refactoring preserves the intended behavior.
PEP 8: conventions, not a proof
PEP 8 discusses readability and consistency. It is a style guide, not a guarantee of functional correctness.
| Topic | Common convention |
|---|---|
| Indentation | Four spaces per level; do not mix tabs and spaces |
| Line length | Normally 79 for code, 72 for comments/docstrings; a team may agree on another limit |
| Blank lines | Two between top-level function/class definitions; one between class methods |
| Functions and variables | snake_case, such as student_count |
| Constants | UPPER_CASE, such as MAX_RETRY |
| Classes | CapWords, such as BankAccount; class syntax comes in L09 |
| Modules and packages | Short lowercase names, such as utils or mypackage |
| Internal use | A leading underscore, such as _helper; this is not access enforcement |
| Confusing names | Avoid single-letter l, O and I |
| Built-in names | Avoid shadowing list, str, sum or type when their built-in meaning is needed |
Continuation lines may align with an opening delimiter or use a hanging indent:
result = some_function(first_argument,
                       second_argument)

result = some_function(
    first_argument,
    second_argument,
)
These are formatting excerpts, not standalone runnable programs. Either side of a binary operator can be a line-break point if the local style is consistent; PEP 8 suggests breaking before the operator in new code:
income = (gross_wages
          + taxable_interest
          - ira_deduction)
Avoid extra whitespace inside brackets and before commas or colons. Keep spaces around assignment and comparison operators. For mixed-precedence expressions, the guide permits judgment about spacing to expose grouping. Spacing does not change precedence, and a style issue need not be a syntax error.
# Recommended layout.
spam(ham[1], {eggs: 2})
if x == 4:
    print(x, y)

# Legal in suitable contexts, but not the recommended layout.
spam( ham[ 1 ], { eggs: 2 } )
Unannotated parameter defaults and keyword arguments have no spaces around =. Annotated defaults do:
def f(x, y=2):
    ...


def g(x: int, y: int = 2) -> int:
    ...
Three tools, three kinds of work
| Work | Example | What it checks or changes |
|---|---|---|
| Formatting | ruff format file.py, or Black | Layout and whitespace |
| Linting | ruff check file.py | Enabled static rules, such as unused imports or undefined names |
| Behavioral testing | Execute chosen cases and compare results | Specific requirements |
Ruff only checks the selected rules. Its defaults are not “all of PEP 8”, and an empty diagnostic report does not certify the program’s logic. A formatter will not decide what averaging an empty list should mean.
python3 -m pip install ruff
ruff check file.py
ruff format --check file.py     # check without rewriting
The VS Code Ruff extension is another route. If pip reports an externally managed environment, do not force an administrator-level installation; use the course’s Python installation or the editor extension. L10 covers virtual environments. Black is an alternative formatter, not an additional mandatory installation.
Further reading 4. Tests, counterexamples and debugging
Expected results come from the contract
For max_gap, specify an integer list, the largest adjacent gap after sorting, a result of zero for fewer than two elements and unchanged input.
| Input | Expected | Purpose |
|---|---|---|
[3, 9, 1, 15] | 6 | An unsorted ordinary input |
[] | 0 | Empty input |
[7] | 0 | One element |
[2, 2, 2] | 0 | Repeated values |
[-3, -1, -10] | 7 | Negative values |
The candidate omits the short-input case:
def max_gap(nums: list[int]) -> int:
    ordered = sorted(nums)
    gaps = [ordered[i + 1] - ordered[i]
            for i in range(len(ordered) - 1)]
    return max(gaps)

print(max_gap([7]))
The list of gaps is empty, so max() raises ValueError. After a correction, recheck the failure and previously working cases:
def max_gap(nums: list[int]) -> int:
    if len(nums) < 2:
        return 0
    ordered = sorted(nums)
    gaps = [ordered[i + 1] - ordered[i]
            for i in range(len(ordered) - 1)]
    return max(gaps)

for nums, expected in [([3, 9, 1, 15], 6), ([7], 0), ([], 0)]:
    before = nums.copy()
    got = max_gap(nums)
    print(got == expected, nums == before)
This is a regression check. A finite suite can expose defects, but generally does not prove correctness on every input. Read the bounds, conditions and state changes as well.
Useful review dimensions include empty input, one element, repeated values, zero and negatives, scale, output order and mutation. Wrong-type handling is contract-dependent: do not silently require a function specified for integer lists to accept every possible object.
Read the traceback as a record
| Exception | Typical meaning or example |
|---|---|
SyntaxError | Invalid syntax, such as a missing colon |
IndentationError | Invalid indentation structure |
NameError | A name has not been defined |
TypeError | An operation or call rejects the type/argument form |
ValueError | A value violates the interface requirement, such as int("abc") |
IndexError | A sequence index is outside its range |
KeyError | Direct indexing requests a missing dictionary key |
ZeroDivisionError | A divisor is zero |
AttributeError | An attribute or method is unavailable on the object |
RecursionError | Execution exceeds the interpreter’s recursion-depth limit |
A traceback contains call locations and the failing statement; its final line normally names the exception and message. Source lines and caret markers may intervene, so “the second-to-last line is the error location” is not a reliable rule. A recursion-depth failure can come from faulty recursion or a valid but too-deep input. Exception-handling syntax comes in L11.
Observe the state of a failing case
The following candidate is meant to return the longest run of ones from a list containing only zero and one; empty input returns zero:
def longest_run(bits: list[int]) -> int:
    current = 0
    best = 0
    for bit in bits:
        if bit == 1:
            current += 1
        else:
            best = max(best, current)
            current = 0
    return best

print(longest_run([1, 1, 0]))
print(longest_run([1, 1, 0, 1, 1, 1]))
Both calls return 2, but the second should return 3. Just before return, best=2 and current=3. The final run never met a zero, so it was not included in best.
A temporary print can expose these values. Alternatively, pause on the return statement in VS Code:
- Enable the Python and Python Debugger extensions and select the course interpreter.
- Click the gutter beside the return statement to set a breakpoint.
- Start from Run and Debug; execution pauses before that statement runs.
- Inspect the selected frame’s variables, or add
bestandcurrentto Watch.
| Action | Common shortcut | Behavior |
|---|---|---|
| Continue | F5 | Resume until a breakpoint or completion |
| Step Over | F10 | Execute the line without entering the called function |
| Step Into | F11 | Enter a function called on the line |
| Step Out | Shift+F11 | Finish the current function and return to the caller |
The operating system, keyboard and custom bindings can change shortcuts; some keyboards need Fn. The toolbar action names are another way to operate the debugger. Watch evaluates in the selected context when execution pauses, not continuously during execution.
For this contract, include the unfinished run when returning:
def longest_run(bits: list[int]) -> int:
    current = 0
    best = 0
    for bit in bits:
        if bit == 1:
            current += 1
        else:
            best = max(best, current)
            current = 0
    return max(best, current)

for bits in [[], [0], [1], [1, 1, 0], [1, 1, 0, 1, 1, 1]]:
    print(bits, longest_run(bits))
Select a recursive frame
When L07’s factorial(3) has entered factorial(1), three calls are active with local n values 1, 2 and 3. Selecting the outer frame shows its own n=3; the inner call has not overwritten it.
Print is convenient for a few values or a batch log. A debugger is convenient for pausing, stepping and selecting frames. Both remain useful; neither is a universal replacement for the other.
Further reading 5. Correct answers at the required scale
This deduplication preserves first-occurrence order:
def dedup(items: list[int]) -> list[int]:
    result = []
    for x in items:
        if x not in result:
            result.append(x)
    return result

print(dedup([3, 1, 3, 5, 1]))
Reading the membership check reveals repeated searches through a growing list. An explicit search lets us count how many existing elements are examined:
def dedup_counted(items: list[int]) -> tuple[list[int], int]:
    result = []
    comparisons = 0
    for x in items:
        found = False
        for old in result:
            comparisons += 1
            if old == x:
                found = True
                break
        if not found:
            result.append(x)
    return result, comparisons

for n in [10, 100, 1000]:
    result, checks = dedup_counted(list(range(n)) * 2)
    print(n, checks)
For this particular input—n distinct elements appearing twice in the same order—the explicit comparison count is n². That is not a measurement of CPython machine instructions, nor a claim that all distributions use exactly n² checks.
A set can record seen integers while a list retains result order:
def dedup(items: list[int]) -> list[int]:
    seen = set()
    result = []
    for x in items:
        if x not in seen:
            seen.add(x)
            result.append(x)
    return result

for items in [[], [3, 1, 3, 5, 1], [-1, 0, -1]]:
    before = items.copy()
    print(dedup(items), items == before)
Set lookup has a favorable average cost; it is not guaranteed to be a single step. This interface uses hashable integers, not arbitrary nested lists.
A timing comparison must use comparable data, environments and measurement methods, and first establish equivalent results. Hardware, runtimes and other work affect elapsed seconds. One observed speedup is not a universal ratio. L11 develops the time/space analysis formally.
Further reading 6. Review, acceptance and disclosure
Four candidates, different questions
The lecture has used four review tasks:
items.remove_all(value): determine API availability through documentation and execution.max_gap: expose an omitted boundary with a short input.dedup: identify repeated list search and check the amount of work.f(l,D): recover the behavior, improve readability and check equivalence.
Do not assume that every candidate has exactly one defect. Do not classify behavior outside the stated domain as a defect without first checking the requirement.
A precise IPv4 exercise
Lab08 uses is_valid_ipv4(s: str) -> bool. Its string inputs follow this strict dotted-decimal contract:
- exactly four parts separated by
.; - ASCII digits
0through9only, each value in 0–255; - the single digit
0is allowed; other leading-zero forms are not; - no empty parts, signs or surrounding/internal whitespace.
Write independent tests before inspecting a candidate. Valid cases can include 0.0.0.0, 192.168.1.1 and 255.255.255.255. Invalid cases should cover part count, range, leading zeros and character restrictions. The full corrected lab solution is not supplied here.
A documented conversion may accept more than the task permits, and a familiar character predicate may be broader than expected:
for s in ["01", "+1", " 1", "1"]:
    print(repr(s), int(s))

for s in ["1", "1", "²"]:
    print(repr(s), s.isdigit())
The ASCII restriction is explicit in this exercise. Python’s ipaddress documentation states the four-part and leading-zero requirements but does not spell out that character restriction on the referenced page. Keep documented claims, observed behavior and the task’s own contract distinct.
Division of work and safe use
| Stage | Work to retain |
|---|---|
| Understand and decompose | Decide goals, inputs, outputs and interfaces |
| Implement | Own the main code; ask chat for limited code suggestions |
| Review | Understand state, unfamiliar APIs and side effects |
| Test | Design checks from the contract; tools may add suggestions |
| Correct | Keep the counterexample, original candidate and change scope |
| Accept | Explain the evidence and take responsibility for the submitted code |
Work out the task before implementing it. Check unfamiliar constructions against documentation and the runtime. Make the function work, then decide what the required input sizes demand; avoiding premature optimization does not excuse an obviously unsuitable design.
Remove personal information, tokens, passwords and keys before sending material to an external tool. Do not run unfamiliar file operations, installations or network requests without inspecting them. Keep teaching failures small and within an environment you control.
An AI usage declaration
At Level 1, use chat for local code assistance and debugging, not complete assigned solutions or coding-agent project operations. Disclose the tool, local generated or revised scope and the checks you actually ran. This is a format example, not a real usage log:
AI usage declaration:
Tool and model: record what was actually used; say if the model is unknown.
Generated/revised scope: for example, the single suffix-normalization line.
Manual changes: identify the functions, conditions or blocks changed.
Verification: actual inputs, expected and observed results; input preservation.
Independent work: identify the parts completed without AI.
“An AI said it was correct” is not a test record. If an online tool was unavailable and the instructor’s candidate was used, disclose that source rather than inventing a conversation. If no AI was used, state that explicitly.
Solo assignment 1 remains Level 0, covers ordinary and adjacent-peg Hanoi and is worth 5% of the semester grade. Its deadline is on the submission page. This week’s Level 1 does not change that assignment’s rule. Do not send its implementation to an AI for generation or rewriting; this lecture uses separate classroom examples such as factorial.
Further reading 7. Reference material and legacy exercises
Imports, comments and layout details
Keep these as reference checks:
- Put imports after the module docstring; group standard library, third-party and project imports with blank lines. Avoid wildcard imports whose names may shadow others.
- Prefer implicit continuation inside brackets; avoid trailing whitespace and multiple statements crowded onto a line.
- A one-element tuple needs a comma; use trailing commas in multiline constructs according to the guide and project conventions.
- Comments should explain reasons and stay synchronized with the code. Docstrings state purpose, parameters and results.
- Python 3 source defaults to UTF-8. Keep quoting consistent without treating one quote style as uniquely valid.
- Class, inheritance, public-interface and exception-naming conventions become useful as later lectures introduce those constructs; they are not prerequisites now.
This import grouping is a formatting excerpt; it does not assume that the third-party and project modules are installed:
import os
import sys

import numpy as np

from mypackage import helper
Consult the full PEP 8 for details. The Zen of Python is available through:
import thisTim Peters wrote these principles. Readability and explicitness describe design choices, not a line-by-line correctness certificate.
Leap years: equivalent implementations
For positive Gregorian years, the rule is divisibility by four but not one hundred, or divisibility by four hundred. These three structures express that rule:
def leap_separate(year: int) -> bool:
    if year % 4 == 0 and year % 100 != 0:
        return True
    if year % 400 == 0:
        return True
    return False


def leap_branches(year: int) -> bool:
    if year % 4 == 0 and year % 100 != 0:
        return True
    elif year % 400 == 0:
        return True
    else:
        return False


def leap_boolean(year: int) -> bool:
    return (year % 4 == 0 and year % 100 != 0
            or year % 400 == 0)

for year in [1900, 2000, 2024, 2100]:
    print(year, leap_separate(year), leap_branches(year), leap_boolean(year))
Primes: domain and stopping bounds
A prime is an integer greater than one with exactly two positive divisors. Both legacy versions omitted the n<2 guard. Normal positive samples did not expose it.
def prime_slow(n: int) -> bool:
    if n < 2:
        return False
    for divisor in range(2, n):
        if n % divisor == 0:
            return False
    return True


def prime_fast(n: int) -> bool:
    if n < 2:
        return False
    divisor = 2
    while divisor * divisor <= n:
        if n % divisor == 0:
            return False
        divisor += 1
    return True

for n in [-1, 0, 1, 2, 3, 4, 9, 97]:
    print(n, prime_slow(n), prime_fast(n))
A factor above the square root is paired with one below it. Include the equality boundary for perfect squares; integer multiplication avoids using a floating approximation for that decision.
Digit squares and happy numbers
For nonnegative integers, digit-square sums can be computed by arithmetic iteration, recursion or string traversal:
def squares_loop(n: int) -> int:
    total = 0
    while n > 0:
        total += (n % 10) ** 2
        n //= 10
    return total


def squares_recursive(n: int) -> int:
    if n < 10:
        return n * n
    return (n % 10) ** 2 + squares_recursive(n // 10)


def squares_text(n: int) -> int:
    total = 0
    for ch in str(n):
        total += int(ch) ** 2
    return total

for n in [0, 2, 9, 19, 29]:
    print(n, squares_loop(n), squares_recursive(n), squares_text(n))
The old recursive base case returned n: it gave 2 rather than 4 for input 2, although the example 19 happened to work. Small boundary checks matter. Recursion also has a depth limit.
A positive integer is happy if repeated digit-square replacement reaches one. An already visited state means that the deterministic process will repeat:
def sum_digit_squares(n: int) -> int:
    total = 0
    while n > 0:
        total += (n % 10) ** 2
        n //= 10
    return total


def is_happy(n: int) -> bool:
    seen = set()
    while n != 1:
        if n in seen:
            return False
        seen.add(n)
        n = sum_digit_squares(n)
    return True

print(is_happy(19))
print(is_happy(2))
The set records which states occurred, not their multiplicities. That is enough for cycle detection. Zero is outside the positive-input definition.
Runs: consecutive positions matter
The legacy nested-while implementation also finds the longest run of ones. The outer index skips a run already traversed by the inner loop, so nesting alone does not imply quadratic work.
def longest_run(bits: list[int]) -> int:
    best = 0
    i = 0
    while i < len(bits):
        if bits[i] == 1:
            j = i
            while j < len(bits) and bits[j] == 1:
                j += 1
            best = max(best, j - i)
            i = j
        else:
            i += 1
    return best

for bits in [[], [0], [1], [1, 1, 0, 1, 1, 1]]:
    print(bits, longest_run(bits))
A continuous increasing run compares adjacent positions and requires strict increase. Equal values end the current run. It cannot skip a value to form an arbitrary subsequence:
def longest_increasing_run(nums: list[int]) -> int:
    if not nums:
        return 0
    current = 1
    best = 1
    for i in range(1, len(nums)):
        if nums[i] > nums[i - 1]:
            current += 1
        else:
            current = 1
        best = max(best, current)
    return best

for nums in [[], [1, 3, 5, 4, 7], [2, 2, 2], [1]]:
    print(nums, longest_increasing_run(nums))
Anagrams require multiplicities
For lowercase ASCII strings, matching character counts establishes an anagram. Counting and sorting are two possible implementations:
def char_counts(s: str) -> dict[str, int]:
    counts = {}
    for ch in s:
        counts[ch] = counts.get(ch, 0) + 1
    return counts


def anagram_counts(s: str, t: str) -> bool:
    return char_counts(s) == char_counts(t)


def anagram_sorted(s: str, t: str) -> bool:
    return sorted(s) == sorted(t)

for s, t in [("anagram", "nagaram"), ("rat", "car"), ("aab", "abb"), ("", "")]:
    print(s, t, anagram_counts(s, t), anagram_sorted(s, t))
set("aab") equals set("abb"), but the multiplicities differ. Sets do not preserve the information this task needs.
Simplification and development habits
For an actual bool parameter, if flag is straightforward. For a general object, truthiness is not always equivalent to flag == True. Similarly, L05’s += and + examples show that a shorter spelling can change mutation behavior.
Retain useful habits from the old lecture: plan the task and intermediate state, separate functions by interfaces, test a completed small piece, reuse computed results, name constants, check unfamiliar APIs and preserve failures. Function length, loop depth or brevity do not prove correctness; append() also has appropriate uses.
Summary
Acceptance combines a contract, code review, documentation and runtime checks, targeted tests, mutation checks and scale considerations. A tool run is evidence; a finite test suite is not generally a proof for every input.
Formatters, linters, print and debuggers solve different problems. Preserve the original candidate, failures, modifications and regression results so the acceptance decision can be explained.
L09 asks how the data and operations of similar records can be organized together using classes.
Exercises
- Investigate the candidate below on both nonempty and empty input. Revised contract: return an empty string for empty input; when frequencies tie, return the first word encountered. Correct it and test that contract.
def most_common(words: list[str]) -> str: counts = {} for word in words: counts[word] += 1 return max(counts, key=counts.get) - Specify a function converting scores into letter grades. Include a signature, behavior and at least three examples. Decide score bounds, grade thresholds, empty-input behavior and mutation.
- Write at least six tests from this lecture’s IPv4 contract before examining an AI or instructor-provided candidate. Record expected/observed results and a correction.
- Compare recursive and iterative versions of the classroom
factorial()function, including n=0. AI assistance may follow this week’s policy; do not ask it to rewrite Solo assignment 1. - Run Ruff on your own Labs 1–7 code and explain three unfamiliar diagnostics. If fewer exist, use Lab08’s practice file rather than inventing warnings.
- Read PEP 8’s “A Foolish Consistency is the Hobgoblin of Little Minds” and summarize how local consistency and readability differ from mechanically applying rules.
See Lab08 for the actual tasks, records and submission instructions. The policy is on the AI policy page.